News & releases

Blog

Commentary, releases, and updates from LAION and the open scientific community.

Follow via RSS

4 min read

LAION-BVD: A 10-Million-Hour Open Video Dataset for Multimodal Research

Today we are releasing LAION-BVD (Big Video Dataset), a large-scale open video dataset designed for multimodal machine learning research. LAION-BVD contains: 1.3 billion platform-specific video URLs collected from Common Crawl 80 million downloaded videos 10 m…

Andreas Hochlehnert, Marianna Nezhurina, Mehdi Cherti, Andrej Radonjic, Thaddäus Wiedemer, Christoph Schuhmann, Romain Beaumont, Wieland Brendel, Bernhard Schölkopf, A. Sophia Koepke, Jenia Jitsev, Matthias Bethge

15 min read

Do They See What We See?

Building Emotionally Intelligent AI with EmoNet, a suite of open tools and resources developed by the LAION community A LAION & Intel Collaboration Authors LAIO…

LAION

2 min read

LAION-DISCO-12M

LAION announces the LAION-DISCO-12M - a collection of 12 million links to publicly available YouTube samples paired with metadata to support basic machine learn…

LAION e.V.

3 min read

Open Empathic Launch

We are thrilled to present Open Empathic , a pioneering open-source project initiated by our non-profit organization, LAION. Open Empathic aims to equip open-so…

Christoph, Knoriy, Robert

8 min read

LeoLM: Igniting German-Language LLM Research

We proudly introduce LeoLM ( L inguistically E nhanced O pen L anguage M odel), the first comprehensive suite of German-language Foundation Language Models trai…

Björn Plüster

5 min read

Introducing OpenLM

Introduction We release OpenLM a simple and minimalist PyTorch codebase for training medium-sized language models. OpenLM is designed to maximize GPU utilizatio…

OpenLM team

13 min read

The OIG Dataset

The Open Instruction Generalist (OIG) dataset is a large open source instruction dataset that currently contains 43M instructions. OIG is one of many chatbot da…

By Huu Nguyen - Ontocord.ai, Sameer Suri, Ken Tsui , Shahules786, Together.xyz team, and Christoph Schuhmann - LAION.ai

5 min read

Training Contrastive Captioners

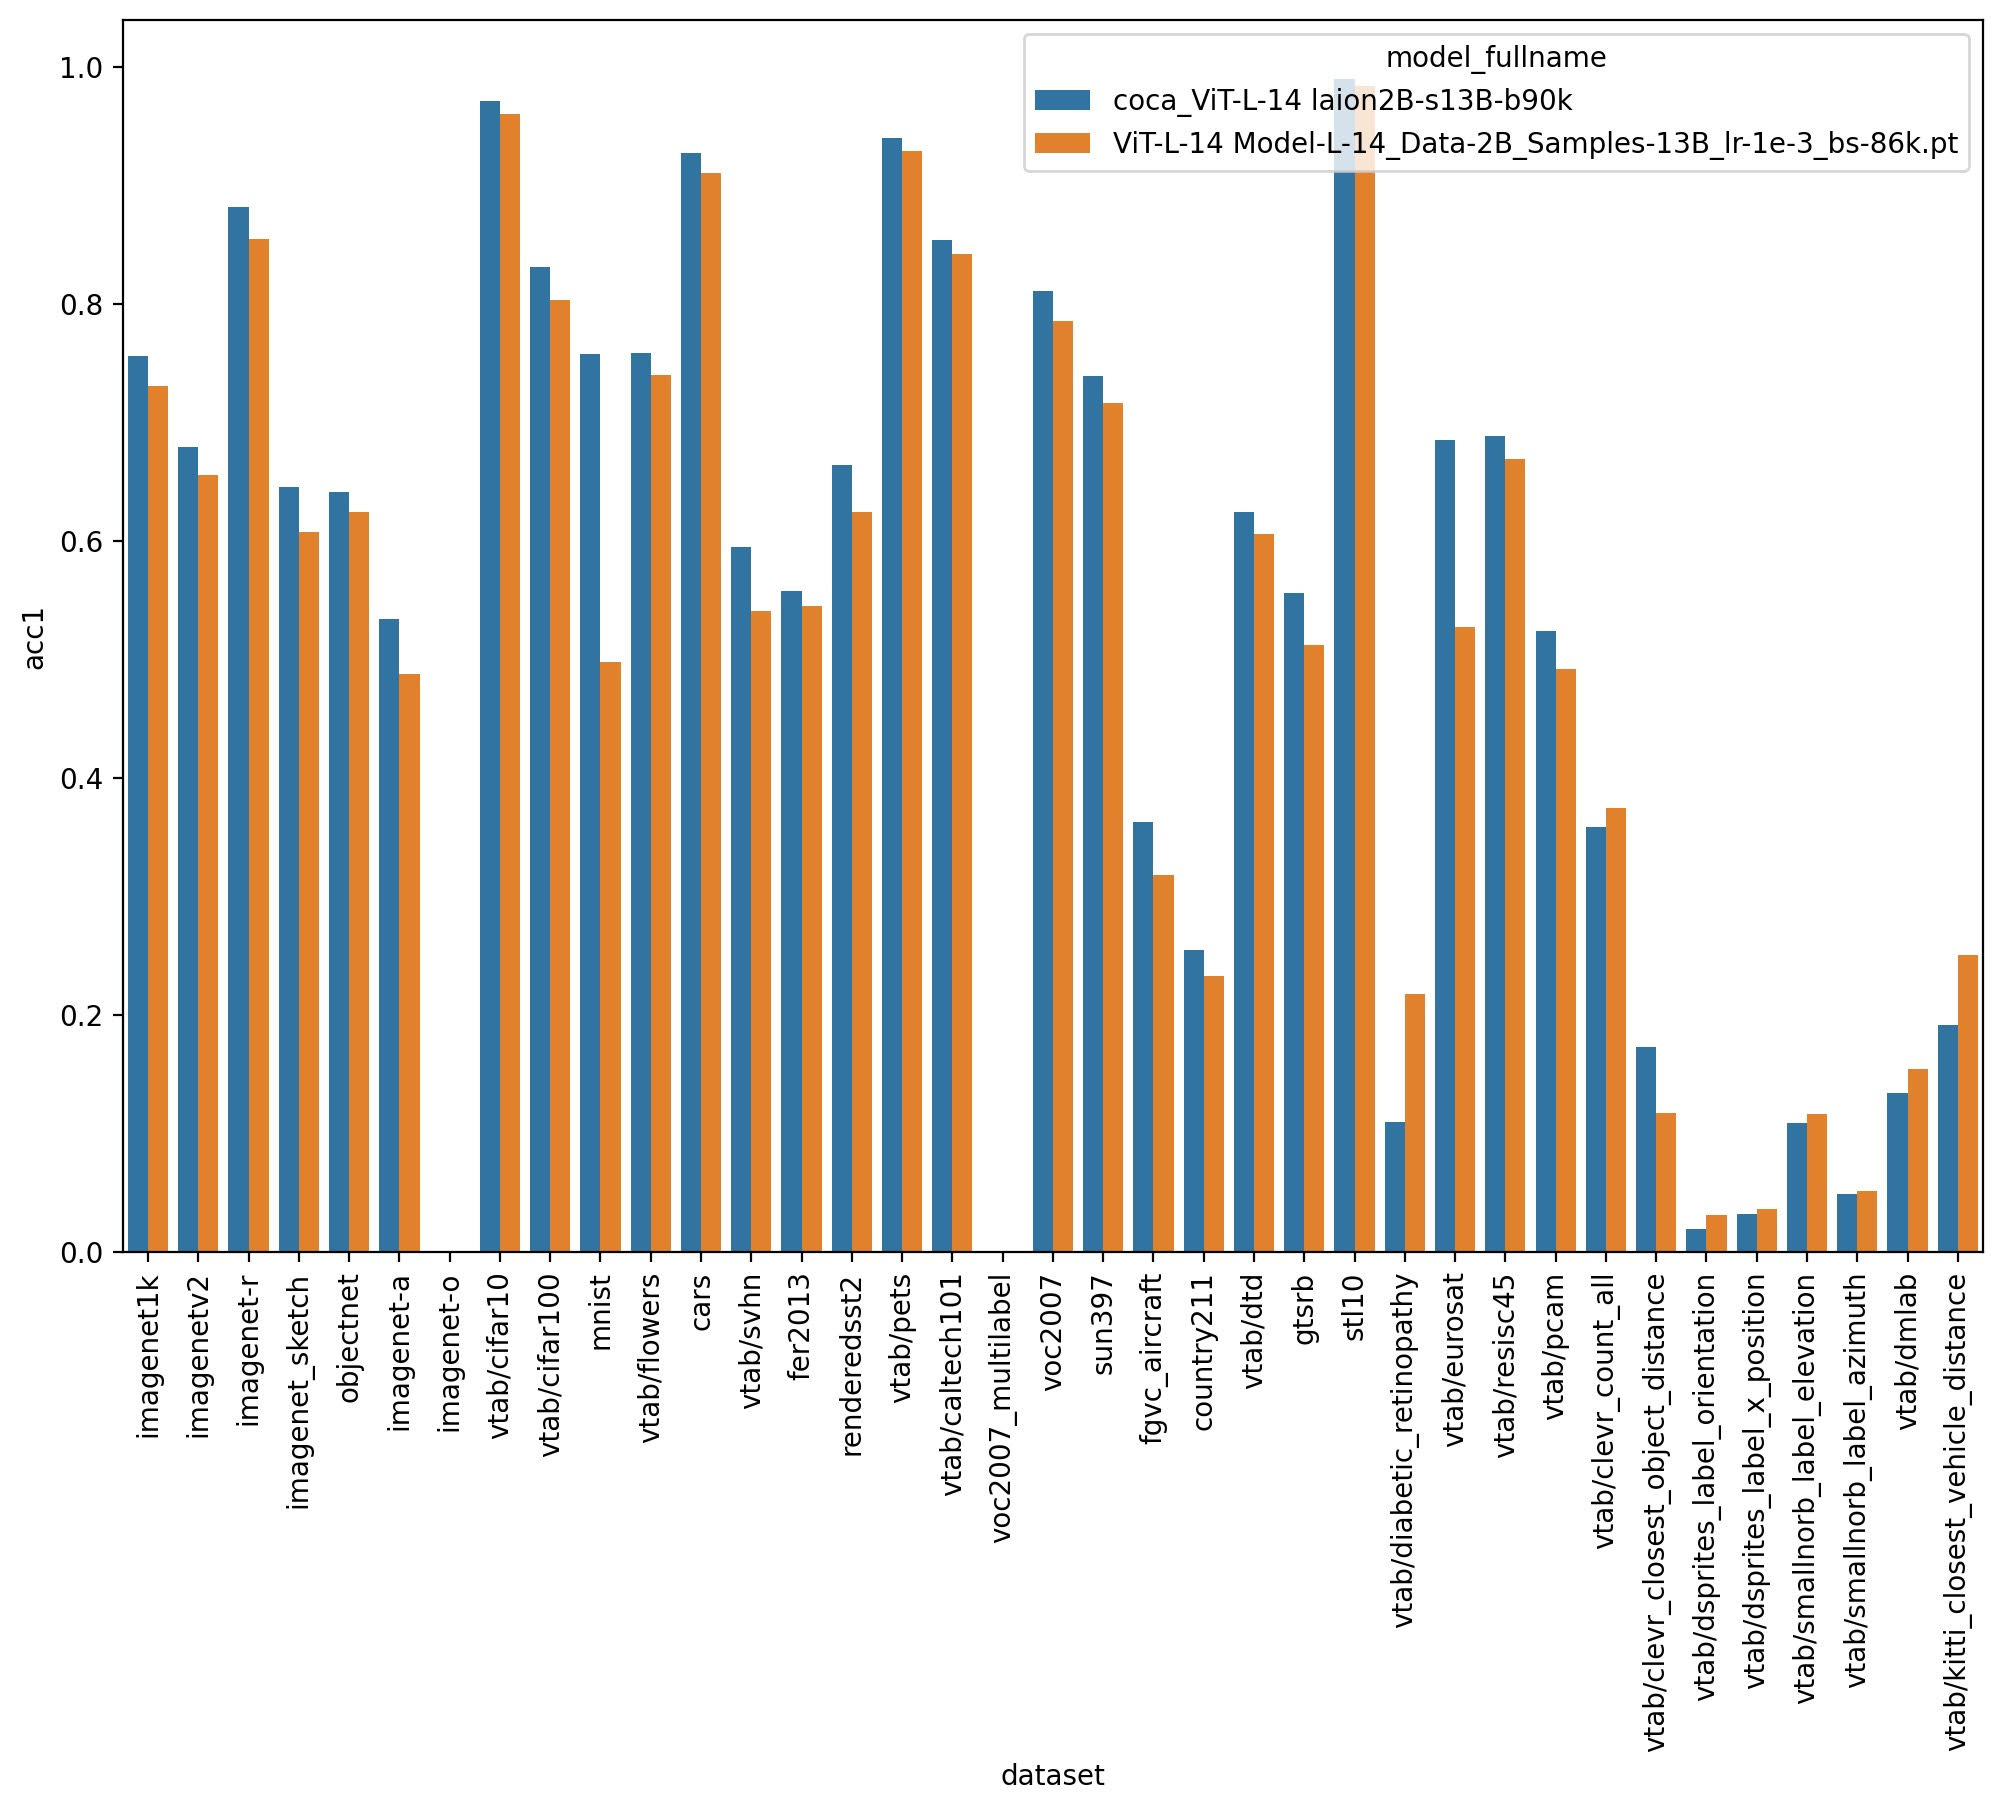
We introduce a new model type to OpenClip Contrastive Captioners (CoCa) [1]. This model adds an autoregressive objective (generation) on top of the CLIP contras…

Giovanni Puccetti, Maciej Kilian, Romain Beaumont

2 min read

Collaboration between LAION and the Stable Horde

Author: Konstantinos Thoukydidis, hlky We are happy to announce that LAION will be assisted by the Stable Horde to provide aesthetic ratings for existing datase…

Konstantinos Thoukydidis, hlky

5 min read

Laion coco: 600M synthetic captions from Laion2B-en

Author: Christoph Schuhmann, Andreas Köpf , Theo Coombes, Richard Vencu, Benjamin Trom , Romain Beaumont We present LAION-COCO, the world’s largest dataset of 6…

Christoph Schuhmann, Andreas Köpf, Richard Vencu, Theo Coombes, Romain Beaumont

5 min read

Laion translated: 3B captions translated to English from laion5B

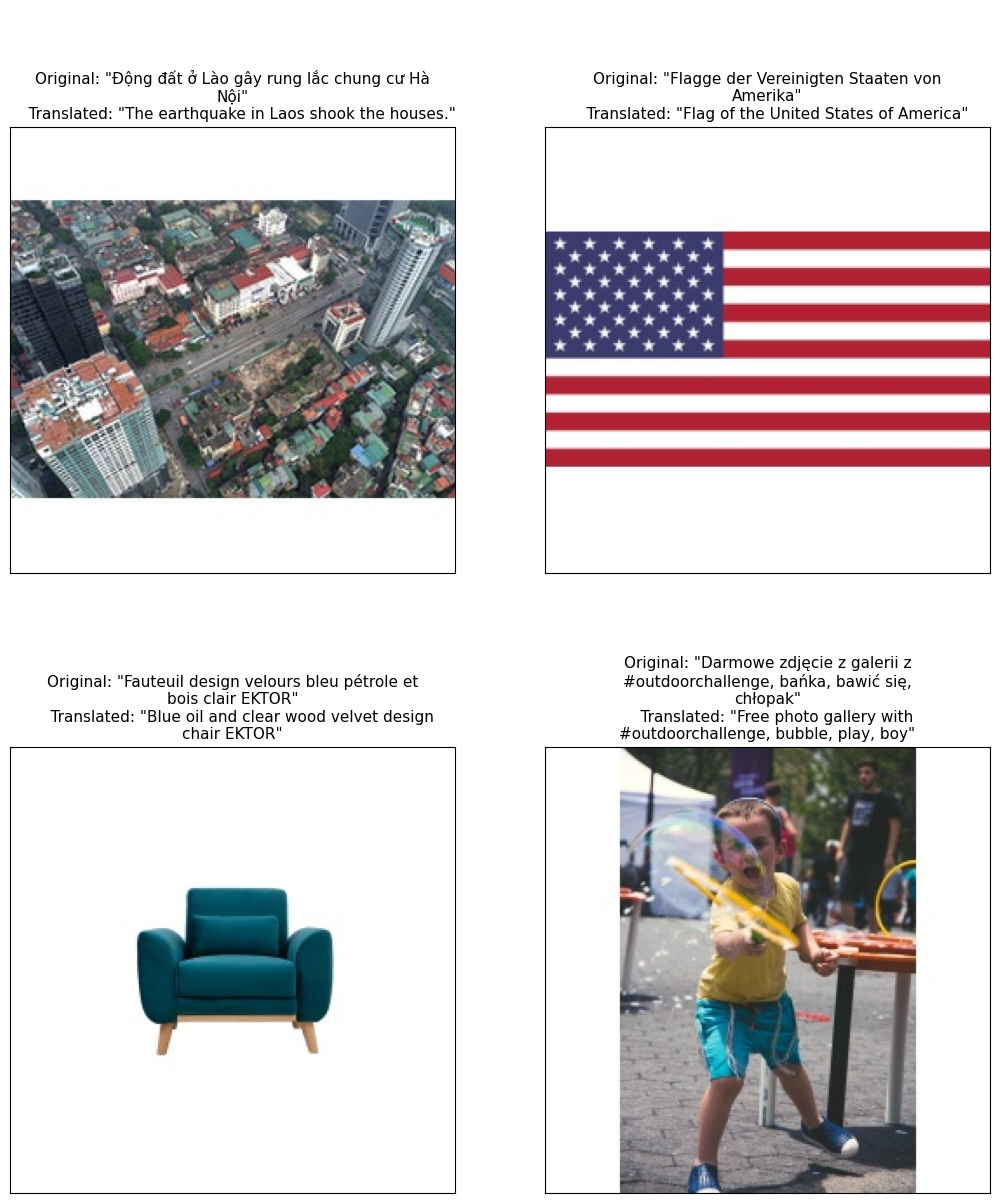
Author: Marianna Nezhurina Romain Beaumont Richard Vencu Christoph Schuhmann Laion5B dataset was automatically collected from a section of the human web (common…

Marianna Nezhurina, Romain Beaumont, Richard Vencu and Christoph Schuhmann

3 min read

LAION-Aesthetics

We present LAION-Aesthetics, several collections of subsets from LAION 5B with high visual quality. To create LAION-Aesthetics we trained several lightweight mo…

Christoph Schuhmann

15 min read

LAION-400-MILLION OPEN DATASET

We present LAION-400M: 400M English (image, text) pairs - see also our Data Centric AI NeurIPS Workshop 2021 paper Concept and Content The LAION-400M dataset is…

Christoph Schuhmann